
Last updated: October 5, 2026
By ZapAI Team
TL;DR: Intelligent document processing on Azure means pairing the right extraction tool with a review process. Use Azure Document Intelligence for structured forms like invoices and receipts, Content Understanding for messy unstructured documents like contracts, and confidence scores to route only uncertain fields to people. Start with one document type, measure straight-through rate, then expand.
Intelligent document processing with Azure AI uses Azure Document Intelligence to extract fields and tables from structured documents, Content Understanding for unstructured ones, and confidence scores to send only uncertain results to human reviewers.
Everyone has a pile. Vendor invoices arriving as PDFs in a shared mailbox. Packing slips photographed on a warehouse phone. Insurance certificates, bills of lading, onboarding forms. Someone retypes them into Dynamics 365 or a spreadsheet. Usually someone expensive. Always someone bored.
The economics are well documented in accounts payable. Ardent Partners’ 2025 research puts the average cost to process a single invoice at $9.40, with top-performing teams spending far less. Most of that gap is manual handling of exceptions and keying. That’s the gap document AI attacks. Directly.
This guide covers intelligent document processing with Azure in practice. Which Azure tool fits which documents, how to design the human review step, what it costs, and where projects stall.
What Is Intelligent Document Processing on Azure?
It’s using Azure AI services to read documents, extract fields, tables, and text into structured data, validate it, and push it into systems like Dynamics 365, with people reviewing only low-confidence results.
Intelligent document processing, or IDP, combines OCR, layout understanding, and AI extraction models to turn PDFs, scans, and photos into structured data a system can use. Plain OCR gives you a wall of text. IDP gives you the invoice number, the vendor, the total, and each line item, with a confidence score for every field. Huge difference.
On Azure, the core service is Azure Document Intelligence, now part of Microsoft Foundry Tools. It includes a Read model for OCR, a Layout model for tables and structure, prebuilt models for common documents, and custom models you train on your own forms. Azure Content Understanding sits beside it for generative, schema-free extraction.
Document Intelligence or Content Understanding?
Use Document Intelligence for structured and semi-structured documents where consistent, deterministic extraction matters. Use Content Understanding for unstructured, variable documents where you need inferred fields without labeled training data.
Microsoft’s own tool selection guidance draws the line clearly. Document Intelligence is purpose-built for precise extraction of tables, key-value pairs, and fields from forms. Content Understanding, built on generative models, handles unstructured documents, varying layouts, and reasoning about content. Microsoft also notes Content Understanding isn’t meant to replace Document Intelligence for deterministic structure extraction.
| Document type | Best Azure tool | Why |
|---|---|---|
| Vendor invoices, receipts | Document Intelligence prebuilt invoice or receipt | Microsoft maintains the field schema, including line items |
| Your own fixed forms, like applications or claims | Document Intelligence custom extraction | Trained on your labeled samples, consistent output |
| IDs, W-2s, tax forms, health insurance cards | Document Intelligence prebuilt models | Specialized models already exist |
| Contracts, policies, letters, doctor notes | Content Understanding | Unstructured text, fields inferred without labels |
| Mixed mailbox with many document kinds | Custom classification, then route to the right extractor | Classify first, extract second |
That last row is where most real projects land. A single AP mailbox contains invoices, credit notes, statements, remittance advice, W-9 requests, and the occasional holiday card from a vendor who likes you, all of which need to be sorted before any extraction model can do its job properly. Classify first. Always.
How Do Confidence Scores Keep Humans in the Loop?
Every extracted field comes with a confidence score. You set thresholds per field, auto-accept high-confidence values, and send low-confidence fields to a reviewer, so people check exceptions instead of every document.
This is the design decision that makes or breaks the project. Get it wrong and nothing else matters. A threshold that’s too strict sends everything to review and nobody sees savings, so the AP team quietly decides the new system is just extra clicks and goes back to keying invoices by hand. Too loose and wrong totals flow into the ledger. We set thresholds field by field, because a 0.85 confidence on a vendor name you can fuzzy-match against the vendor master is fine, while 0.85 on an invoice total isn’t.
- Totals, tax, and bank details. Strict thresholds, plus a math check that line items add up to the total.
- Vendor name? Medium threshold, backed by matching against your Dynamics 365 vendor list.
- Descriptions and memo fields. Loose, since a typo there rarely costs money.
- PO number, cross-checked against open purchase orders in the ERP before anything posts.
Validation against your own data is the quiet multiplier. A model reading an invoice can’t know which purchase order it belongs to. Your ERP can. Use it. Combining extraction confidence with ERP lookups is how teams push straight-through rates up without accepting more risk.
What Does a Typical Azure IDP Pipeline Look Like?
Documents arrive by email or upload, get classified, extracted with Document Intelligence or Content Understanding, validated against business rules, reviewed when confidence is low, and posted into Dynamics 365 or another system.
- Ingest from a mailbox, SharePoint library, scanner, or app upload, usually triggered by Power Automate or Azure Logic Apps.
- Classify the document type when the source is mixed.
- Extract fields and tables with the matching model.
- Validate. Math checks, vendor and PO matching, duplicate detection.
- Review low-confidence fields in a simple Power Apps screen or approval flow.
- Post to the system of record, such as Business Central or Dynamics 365 Finance, and archive the original.
Microsoft publishes a reference version in its document processing architecture, which is worth handing to your Azure team. The reviewer screen is the piece most teams underinvest in. A reviewer who sees the PDF and the extracted fields side by side, with low-confidence values highlighted, works far faster than one toggling between a PDF viewer, an email, and the ERP screen while trying to remember which field they were checking. Small screen. Big payoff.
Do You Even Need a Custom Pipeline?
Not for standard AP in Business Central. Microsoft’s Payables Agent already reads PDF invoices from a mailbox and drafts purchase invoices. Build custom for other document types, other systems, or volumes above its limits.
Bias check. We build custom IDP pipelines, so it would be convenient to tell you every company needs one. Many don’t. If you run Business Central, its Payables Agent uses Azure Document Intelligence under the hood, monitors a mailbox, matches vendors, and drafts purchase documents for review. Microsoft lists its limits plainly. PDFs up to 10 pages and 5 MB, and up to 500 invoices a day.
Custom makes sense when the documents aren’t invoices, when the target system isn’t Business Central, when volumes exceed those limits, or when validation rules get specific. A freight company matching bills of lading to shipments. An insurer reading claim forms. A manufacturer extracting certificates of analysis into quality records. Those need a pipeline built around your rules, which is the work our AI automation team does. Sometimes the pipeline ends in an agent that also chases missing documents, which we cover in building an AI agent for Dynamics 365.
What Does Azure Document Processing Cost?
Azure Document Intelligence is billed per 1,000 pages, with different rates for Read, prebuilt, and custom models, plus a free tier of 500 pages a month. The bigger costs are build, review labor, and integration.
The Azure Document Intelligence pricing page lists separate meters for Read, prebuilt models, custom extraction, custom classification, and training, with rates that vary by region and agreement, so use the Azure pricing calculator with your real monthly page count. For most mid-market volumes, the Azure service bill is the smallest line in the business case, usually dwarfed by the cost of building the validation rules, the reviewer screen, and the integration into whatever ERP or line-of-business system has to receive the extracted data. Plan accordingly.
Model the business case around labor instead. Count documents per month, minutes of handling each, and the share you expect to process without a human touch. Even a modest improvement in straight-through rate on 5,000 invoices a month frees serious hours. Then subtract review time, because review never drops to zero, and anyone promising 100% touchless processing on day one is selling something. Probably software. Possibly a bridge.
Where IDP Projects Go Wrong
Trying every document type at once, skipping classification, setting one confidence threshold for all fields, and building no reviewer experience. Pick one high-volume document type and do it properly first.
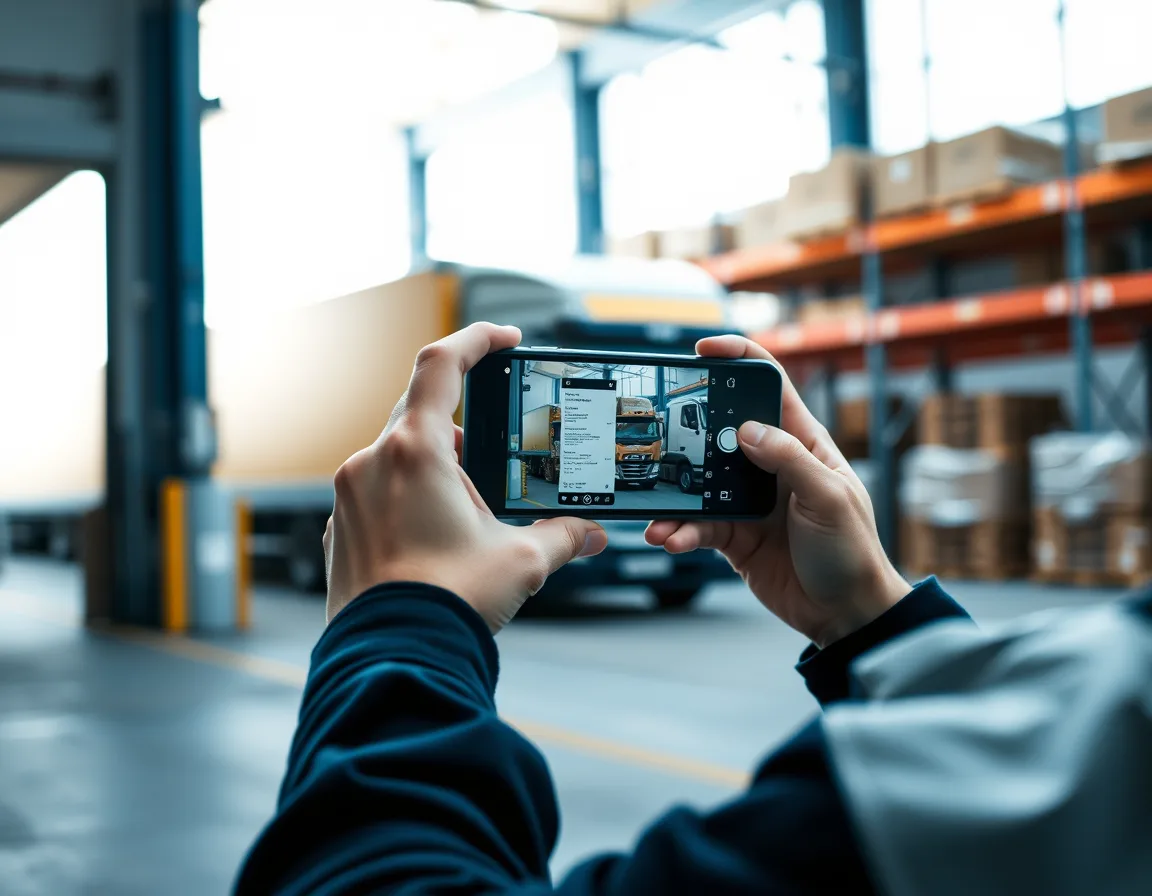
Scanned image quality is the other trap. Phone photos of crumpled delivery notes in a dark truck cab will defeat any model. Fixing capture, with a simple app that guides the photo or a scanner at the dock, often lifts accuracy more than any model tuning, because no amount of clever AI can read a total that’s hidden under a thumb, a coffee stain, or a fold in the paper. Unglamorous. Effective. Cheap, too.
The Takeaway
Intelligent document processing with Azure works when tool choice matches document type, confidence thresholds match field risk, and reviewers have a fast screen. Document Intelligence handles structured forms, Content Understanding handles messy ones, and your ERP data does the validation.
Want to know what share of your documents could flow straight through? Our document processing team can run a sample of your real files through Azure models and report field-level accuracy before you commit to a build.
Questions About Document AI on Azure
Is Azure Document Intelligence the same as Form Recognizer?
Yes. Form Recognizer was renamed Azure AI Document Intelligence, and it’s now grouped under Microsoft Foundry Tools. Same service lineage, expanded models.
Can it read handwriting?
Partly. The Read model and prebuilt receipt model handle printed and handwritten text, and accuracy depends heavily on legibility and image quality. Test with your own samples before promising anyone touchless processing of handwritten forms.
How many samples do we need for a custom model?
Fewer than people expect for consistent forms. A handful of labeled examples per layout can work for template models, while neural custom models benefit from more varied samples. Content Understanding can extract fields without labeled training data at all.
Where does our document data go?
It’s processed in the Azure region you choose for the resource. Document Intelligence can also run in containers for teams with strict data residency needs, which is worth discussing early with security.
Can Power Automate do this without Azure directly?
For simple cases, yes. AI Builder in Power Automate offers document processing for makers. Larger volumes, custom validation, and multi-system pipelines usually move to Azure Document Intelligence directly for control and cost.
What’s a realistic straight-through rate?
Honestly, it varies too much to quote one number. Document variety, image quality, and how strict your validation rules are all move it. Measure your current touch rate on one document type, run a sample through Azure, and set a target from that baseline rather than from a vendor’s brochure.